Document Memory Agent.
A RAG assistant that answers questions about your documents with cited sources, running free on a local model and measured by its own eval.
- ROLE
- AI Engineer
- TEAM
- Solo
- DATE
- Dec 2025 to Present
- TRACK
- AI
- STACK
- Python, smolagents, Ollama, Streamlit, SQLite, BM25, pytest
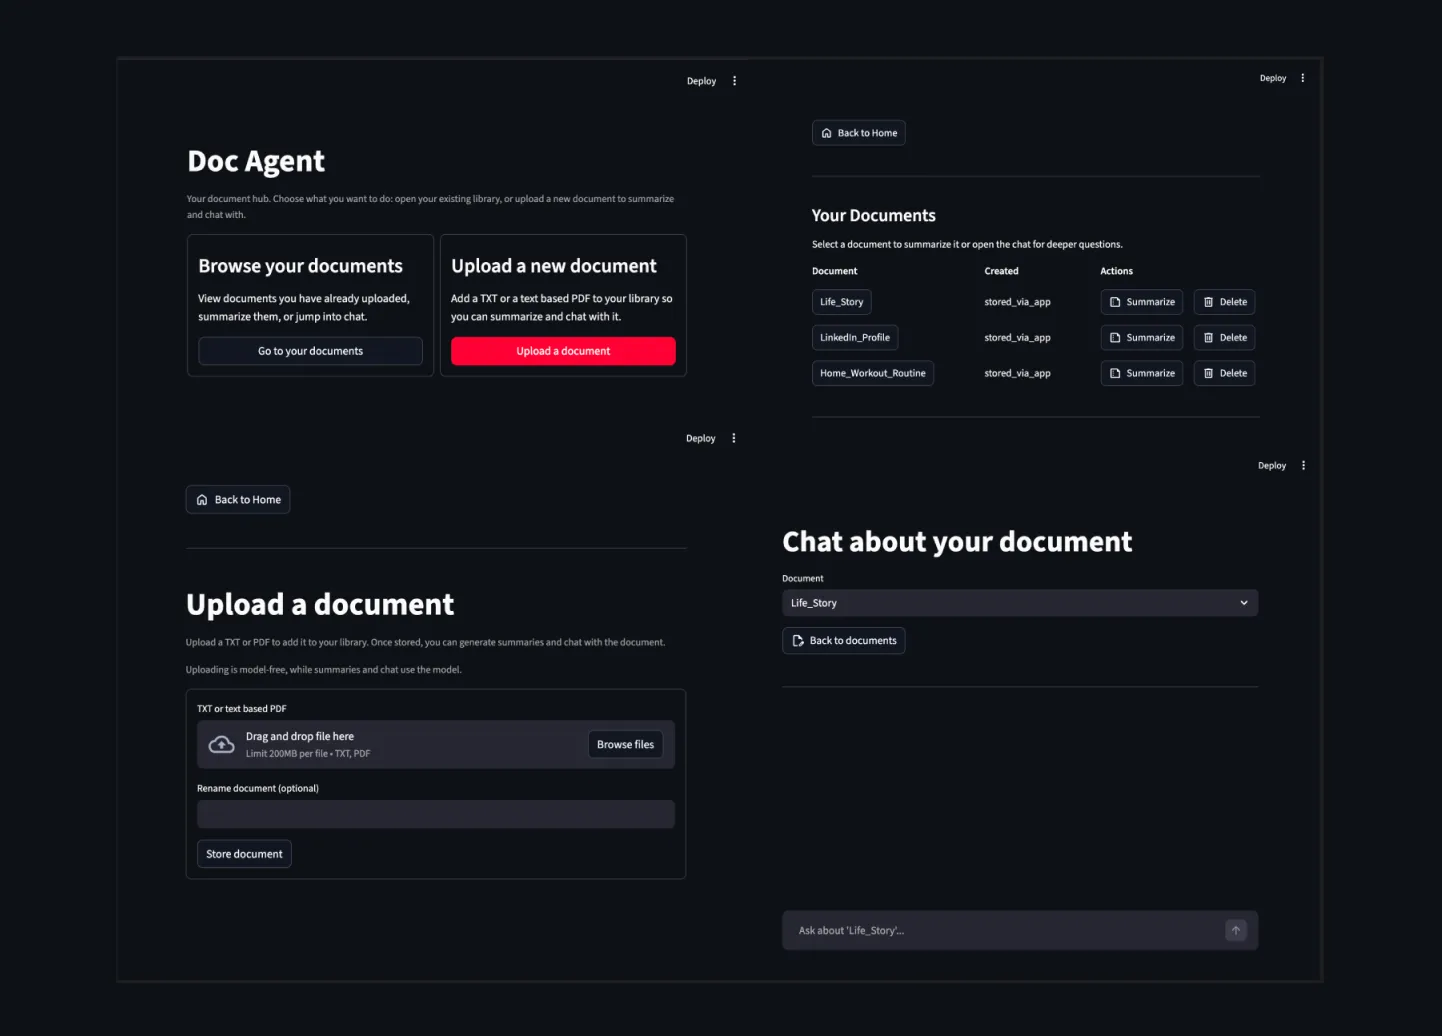
FIG. 03B ARCHITECTURE
- Streamlit app, frontend. Connects to Question agent (QUESTION), Summarizer (SUMMARY). See note 2.
- Question agent, backend. Connects to SQLite + keyword search (SEARCH), Local model (Ollama) (ASK). See note 4.
- Summarizer, backend. Connects to SQLite + keyword search (SAVE), Local model (Ollama) (ASK ONCE). See note 3.
- SQLite + keyword search, storage.
- Local model (Ollama), model. See note 1.
NOTES
Decision
When Hugging Face ended free inference, I moved to a local model served by Ollama through the standard OpenAI-style API. It runs free, documents never leave the machine, and switching to a hosted provider is a config change, not a rewrite.
Trade-off
Free and private came at the price of speed: answers currently take about 34 seconds, because a 28B reasoning model runs on a laptop and the agent calls it at least twice. Lighter thinking, a smaller model or a single call should cut that, and the eval will show what each one costs in quality.
Decision
Not every task needs an agent. A summary is one direct model call, cached in SQLite, so opening it again is instant and free.
What I got wrong
The agent kept searching in loops, and I blamed the model. The bugs were mine: smolagents was silently ignoring my custom prompt, and search results were cut too short to answer from. Fixing both took the eval to 100% correct answers.
RESULTS
- CORRECT ANSWERS, 18-QUESTION EVAL
- 100%
- SAYS "I CAN'T FIND IT" INSTEAD OF GUESSING
- 100%
- AVERAGE ANSWER TIME, LOCAL MODEL
- ~34s
PROJECT 01 / 08