Finderella.
Map of Berlin cafés scored for laptop work by an LLM tool-use agent. I built the Apify review-selection pipeline and now develop the React frontend.
- ROLE
- Full-Stack Developer: frontend and review pipeline
- TEAM
- Started with 9 volunteers (Empowered in Tech & PyLadies Berlin); now the project owner and me
- DATE
- May 2026 to Present
- TRACK
- AIFull-Stack
- STACK
- React, TypeScript, MapLibre, FastAPI, LLM API, Apify, Supabase
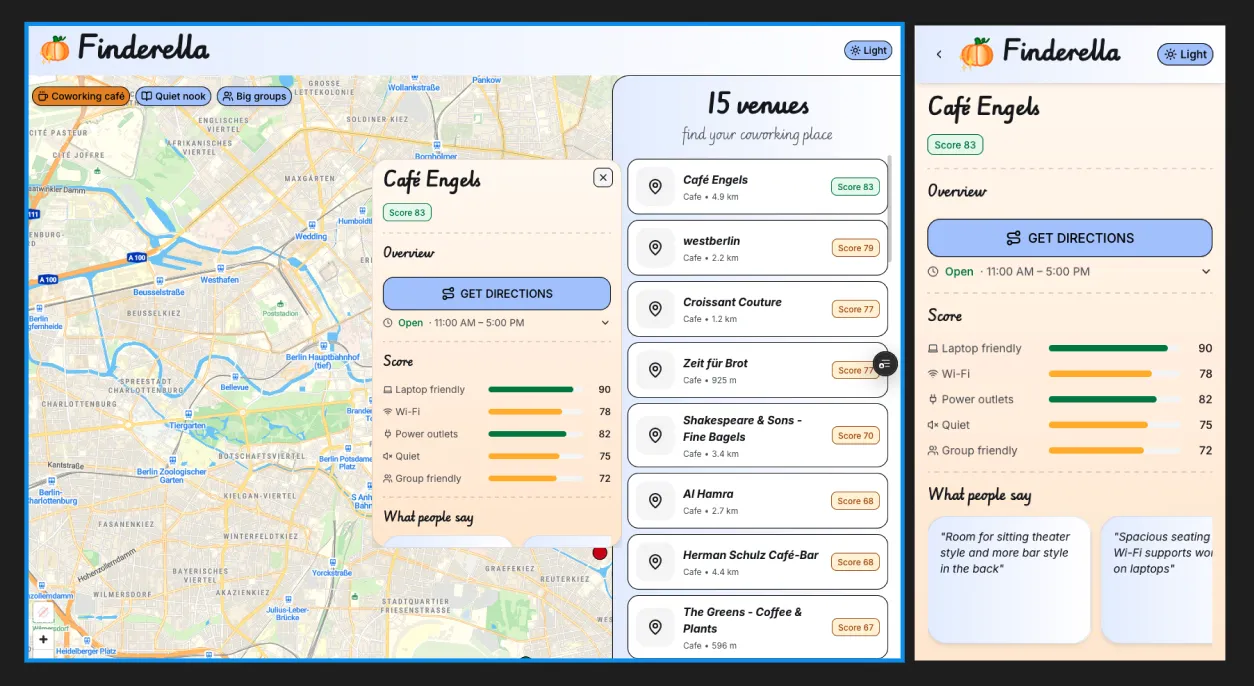
FIG. 03B ARCHITECTURE
- Apify · Google Maps, external. Connects to Review selection (35 REVIEWS). See note 4.
- React PWA, frontend. Connects to FastAPI (HTTPS). See note 3.
- Review selection, backend. Connects to Claude scoring agent (TOP 15). See note 1.
- FastAPI, backend. Connects to Supabase + PostGIS (SQL).
- Claude scoring agent, model. Connects to Supabase + PostGIS (SCORES). See note 2.
- Supabase + PostGIS, storage.
NOTES
Decision
Instead of handing the agent every review, the fetcher pulls the 35 newest from Apify, drops star-only ratings, keeps up to 10 that mention Wi-Fi, outlets, laptops or noise, and fills the last 5 with the most recent. Each review is prefixed with its month so the agent can weigh old complaints less.
Trade-off
Keyword ranking is a plain substring count: cheap, predictable and easy to unit-test, but it misses paraphrases and can't see relevant reviews older than the newest 35. I gave up semantic ranking to keep each venue's Apify bill at about two cents.
Showing uncertain scores
The agent returns a confidence with every score. On the venue page I render a null confidence or a zero score as 'no evidence' rather than a number, and show the review quotes behind each score, so a guessed 50 never looks like a measured one.
What I got wrong
My first fetcher PR was merged too early and reverted the same day: it wrote JSON files, used print, and queried Supabase itself. The rewrite took the place ID from the agent, logged properly, and shipped with 15 unit and 4 integration tests.
RESULTS
- REVIEWS SENT TO THE AGENT, OF THOSE FETCHED
- 15/35
- AVG. MODEL COST PER VENUE, 49 LOGGED RUNS
- $0.04
- TESTS ON THE REVIEW FETCHER
- 19
PROJECT 02 / 08